Joint research lab aims to release 1 million Korean-language training samples in 2027, focusing on data quality over building new AI models
Nvidia and KAIST plan to release at least 1 million Korean-language AI training samples in 2027, seeking to address a shortage of high-quality data that researchers say is limiting the competitiveness of South Korea's homegrown artificial intelligence models.
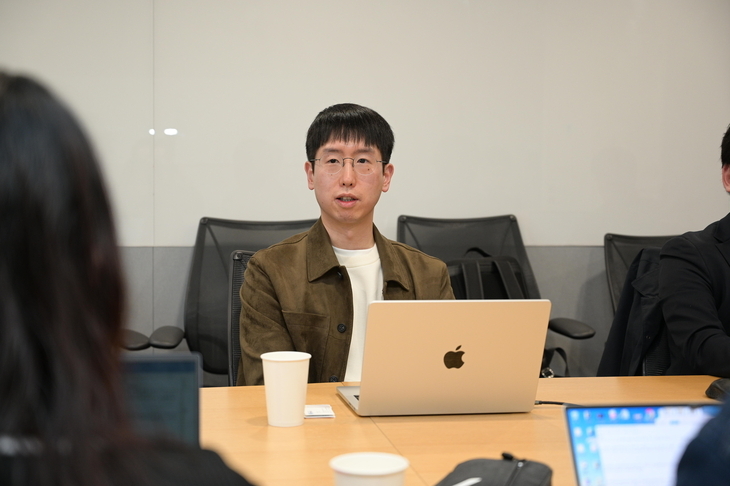
"Our goal is to create at least 1 million Korean-language data samples and make them publicly available for training," Kim Hyun-woo, head of the Nvidia-KAIST Joint AI Research Lab, told reporters in Seoul on Tuesday. No specific release date has been set.
The initiative marks the first concrete research milestone since Nvidia and the Korea Advanced Institute of Science and Technology announced plans in July to establish Asia's first joint AI research lab between Nvidia and a university.
Based at KAIST's Kim Jaechul Graduate School of AI in Seoul, the lab is backed by a five-year, $300 million collaboration focused on Korean-language AI and industry-specific applications.
Kim said Korea has invested heavily in developing AI models and computing infrastructure but has paid comparatively less attention to the high-quality training data needed to make those models competitive.
Rather than developing another foundation model, the lab will focus on generating better Korean-language datasets and improving how existing models learn from them.
Quality over quantity
While Korean-language datasets for evaluating AI models are available, high-quality training material remains limited compared with English and Chinese, Kim said.
Existing datasets often rely on translated text, while AI-generated Korean can contain unnatural expressions. Producing large volumes of synthetic data without proper filtering could also hurt model performance.
"Generating the data itself isn't the problem," Kim said. "Filtering it for quality and curating what matters takes much more effort."
The lab will develop techniques to generate realistic documents from limited information, then refine them for accuracy, diversity and duplication. Kim cautioned that the initial 1 million samples would not be enough to close the language gap.
Nvidia's open Nemotron models will support the research, but the resulting datasets and training methods are intended for broader use by Korean AI developers.
"Nemotron is just one of the trees in the forest," Kim said. "A healthy forest needs different kinds of trees growing together."
An earlier Nvidia initiative, Nemotron-Personas-Korea, generated 7 million synthetic personas based on Korean government statistics. The dataset was used in developing LG AI Research's K-Exaone 2.5 and recorded about 140,000 downloads, according to Kim.
Asked whether publicly releasing Korean-language datasets could also benefit foreign competitors, Kim said strengthening domestic research capabilities was more important than restricting access.
Building research base in Korea
Nvidia has begun recruiting full-time researchers in Korea for its global research organization, with initial hires expected by year-end.
Of the $300 million collaboration, $250 million will come as computing resources provided through Nvidia's Korean cloud partners over five years. The program will also support at least 10 KAIST researchers annually, including internship opportunities at Nvidia.
Once the Korean-language data foundation is established, the lab plans to expand into industry-specific datasets and agentic AI, which can carry out complex tasks with limited human intervention.
Industry partnerships and intellectual property arrangements remain under discussion.
Kim said the research could eventually benefit other languages with relatively limited training data, including Japanese and Indian languages.
"If the data and training methods developed here are widely used by other Korean AI models, I would consider that a success," he said.
yeeun@heraldcorp.com